
Goal Mode + self-verification + regression guards, hundreds of hours of unattended iteration
Back
 We recently launched Computer Use: a capability that lets AI operate real desktop interfaces. The final product matters, but the more interesting story is how we built it.
Computer Use lets AI see the screen, click buttons, type, drag, and keep working in the background without interrupting the user. The hard part is not merely sending an action. The action has to actually take effect, the post-action state has to be readable, and the tool must not steal the foreground.
In practice, this project came with three very concrete challenges:
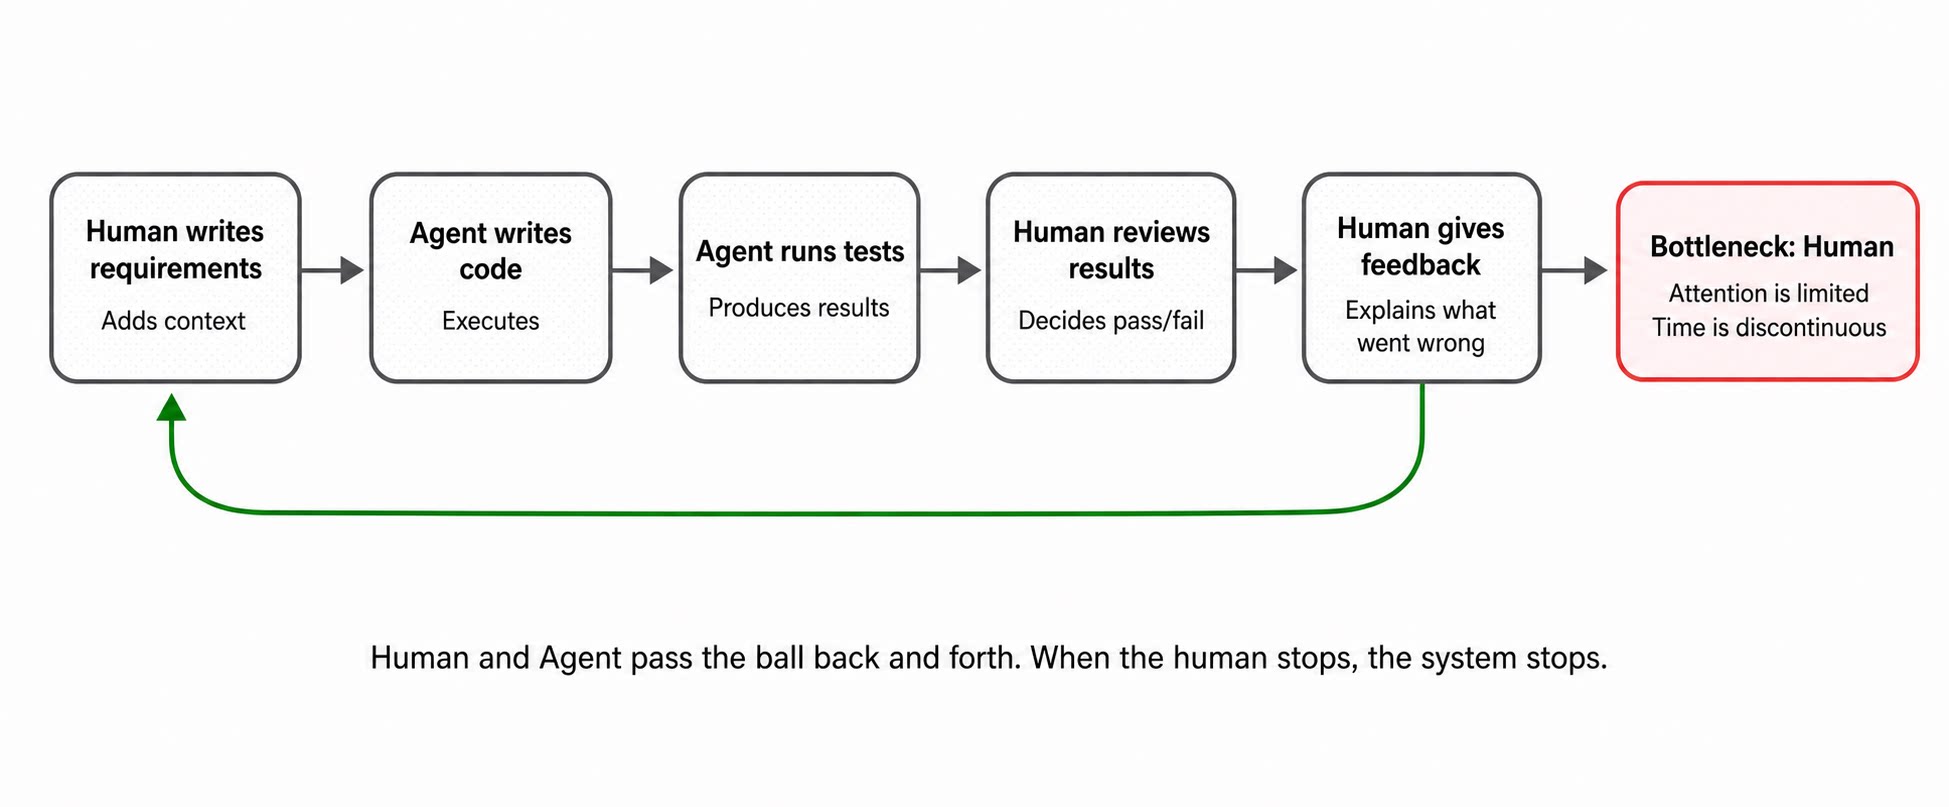
The first workflow was very traditional: I wrote the requirement, the Agent wrote code, I manually ran tests, inspected the result, and then gave feedback.
If you have used AI coding assistants, this probably feels familiar. Every conversation starts from zero. You have to restate the context, explain how to test, and remind the Agent which directions have already failed. The Agent may be capable, but without persistent memory, each round feels like working with a new person.
The bottleneck is the human. Human attention is limited and discontinuous. When the human stops, the system stops. To keep iterating, the system has to be able to run on its own.
To make the Agent iterate autonomously, the first step was to build a pipeline it could complete by itself.
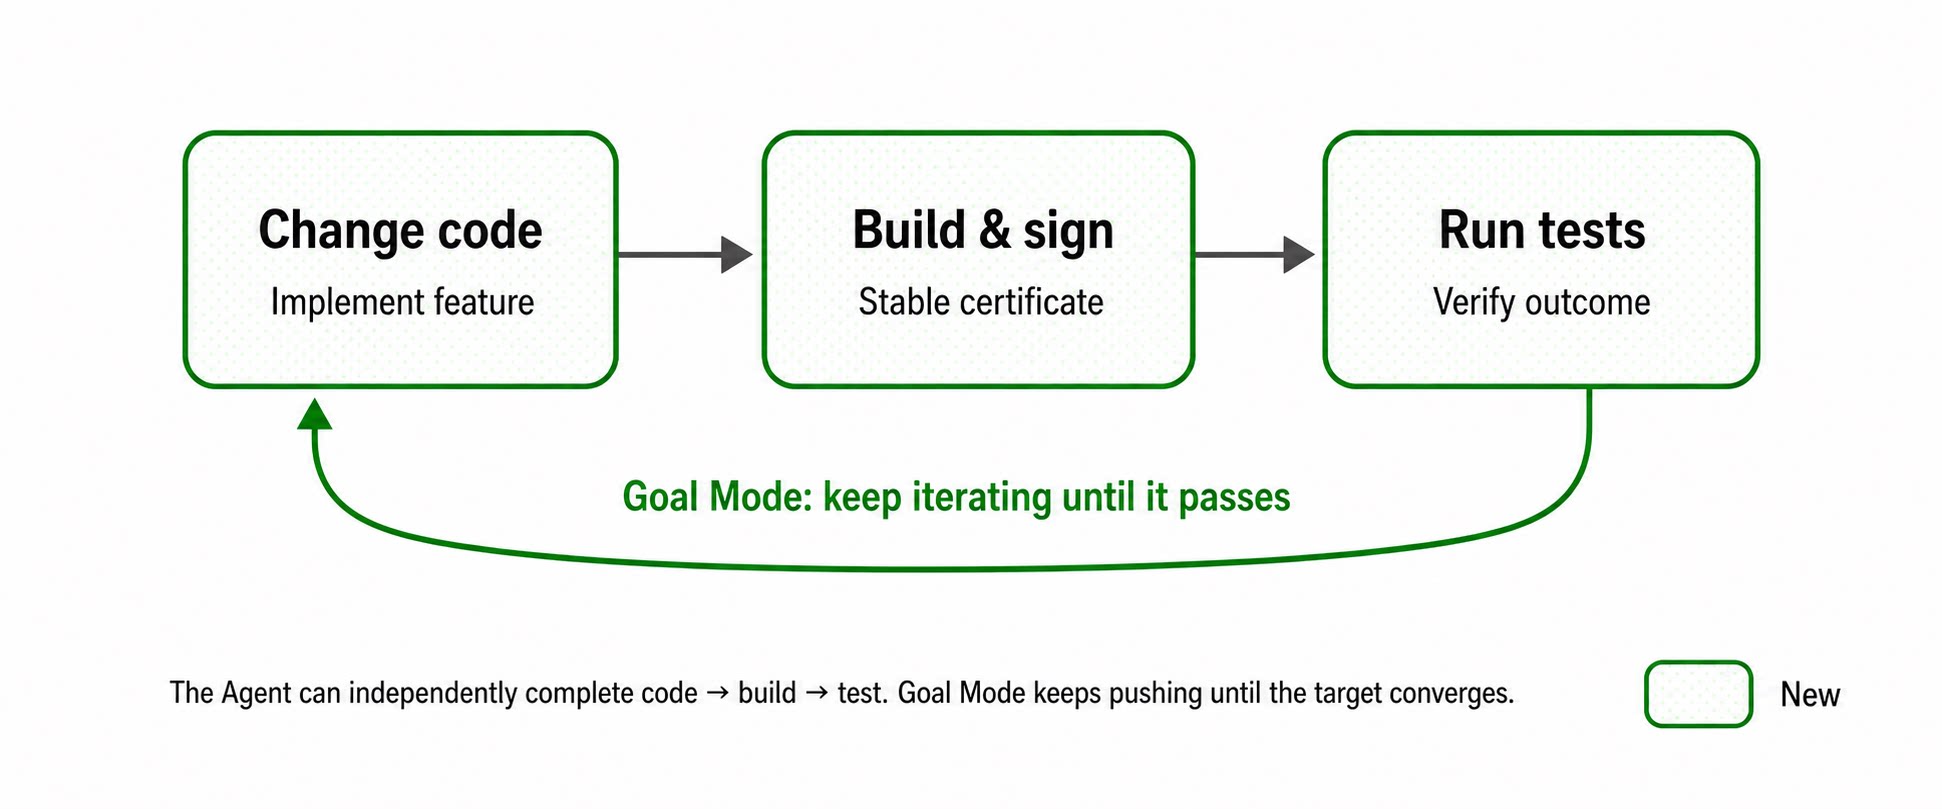
ComputerUse depends on system permissions. Every build has to be signed with the same certificate; otherwise macOS treats it as a new application and invalidates the previously granted Screen Recording and Accessibility permissions. We wrapped the entire path from source build, to stable signing, to launch, to tests. The Agent can run the full path with one command. It does not need to understand signing details; it only needs a reliable route to a behaviorally valid package.
Being able to run once is not enough. A normal Agent conversation is request-and-response: once the task is done, it stops. But building a tool often requires many turns before it converges. Compilation fails, tests fail, behavior is wrong in one app, or a fix causes a regression elsewhere. If a human has to restart every round, the efficiency collapses.
We used Qoder Goal Mode. You give the Agent a goal, such as "implement the click tool and pass the end-to-end test." It keeps working toward that goal: implement, test, fix failures, and try again until it either succeeds or clearly needs a human decision. It no longer "runs once and stops"; it loops until the target converges.
Once the Agent could run by itself, a new problem appeared quickly.
For example, we asked the Agent to implement the click tool. It ran the test and reported success. But when we checked manually, the button had not actually been clicked. The test only checked that the call did not throw; it did not check that the button state changed. The test was green, but the real behavior was wrong.
The issue was not that tests were missing. The issue was that the tests were too weak. If a test only covers the happiest path, the Agent can write an implementation that does nothing and still "pass." We changed the rule: no change is complete unless it passes real and sufficient verification.
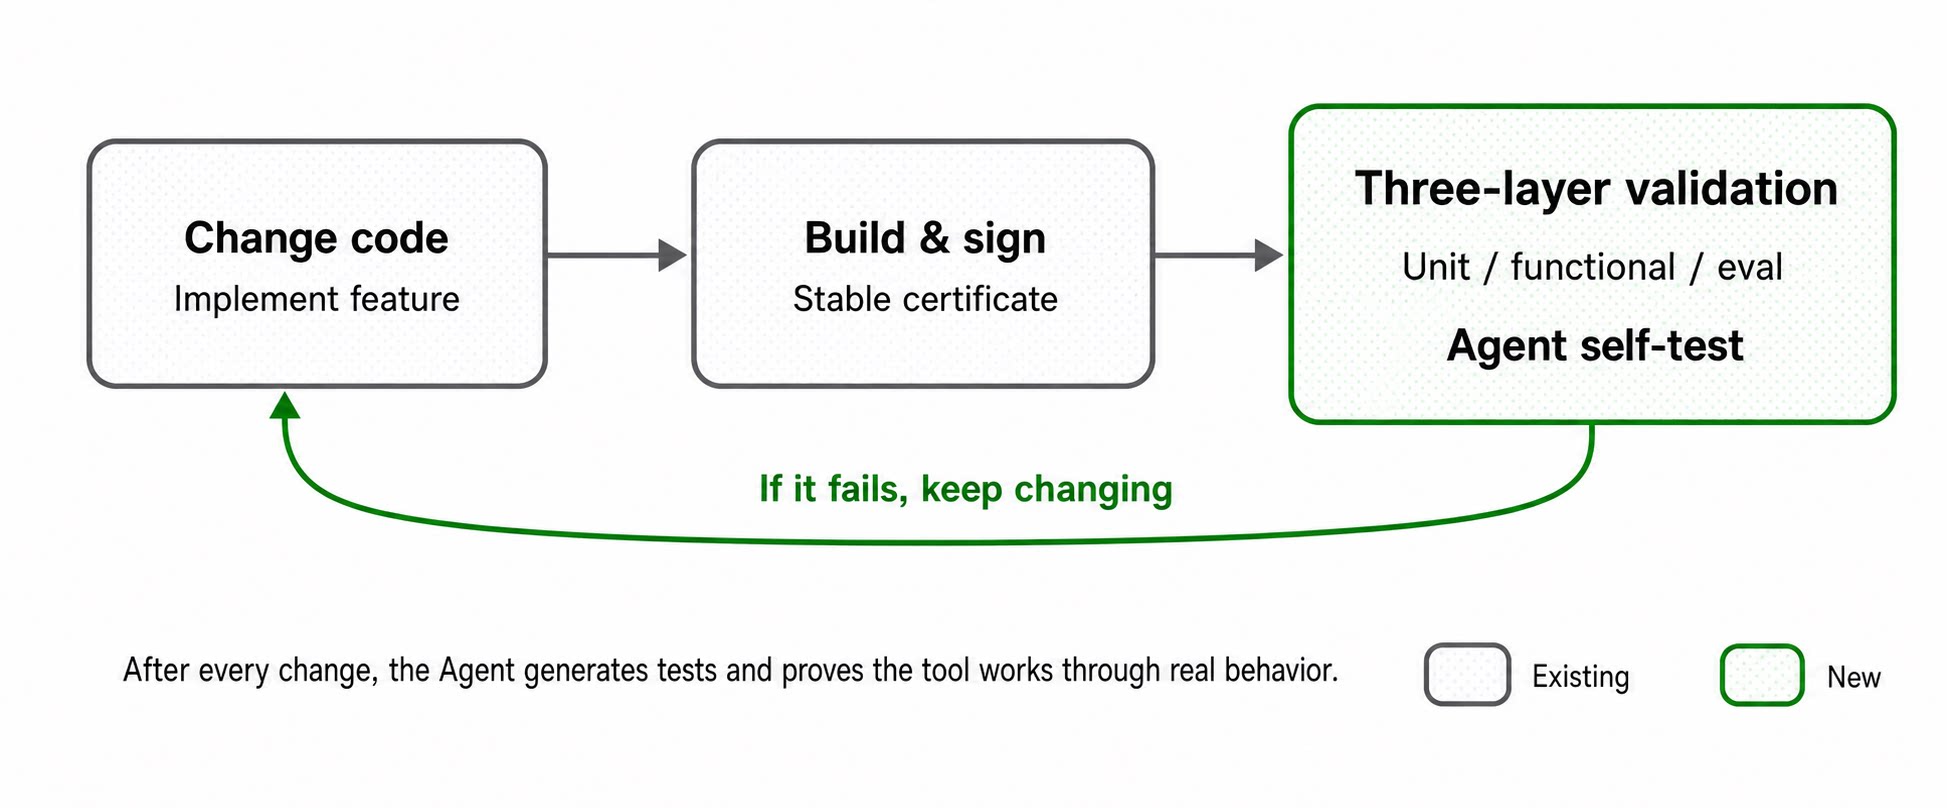
That verification has three layers:
 From single-function tests to full workflow acceptance, the point is not that a tool call returns success. The point is that the final effect is verified from multiple angles.
Verification lets the Agent prove that the current change works. But it does not automatically protect against another class of failure.
Suppose we fix an issue on Monday: clicking a button sometimes steals foreground focus. On Wednesday, the Agent optimizes another feature and accidentally changes related logic. The old issue comes back, but no one notices because it is outside the current task's test scope.
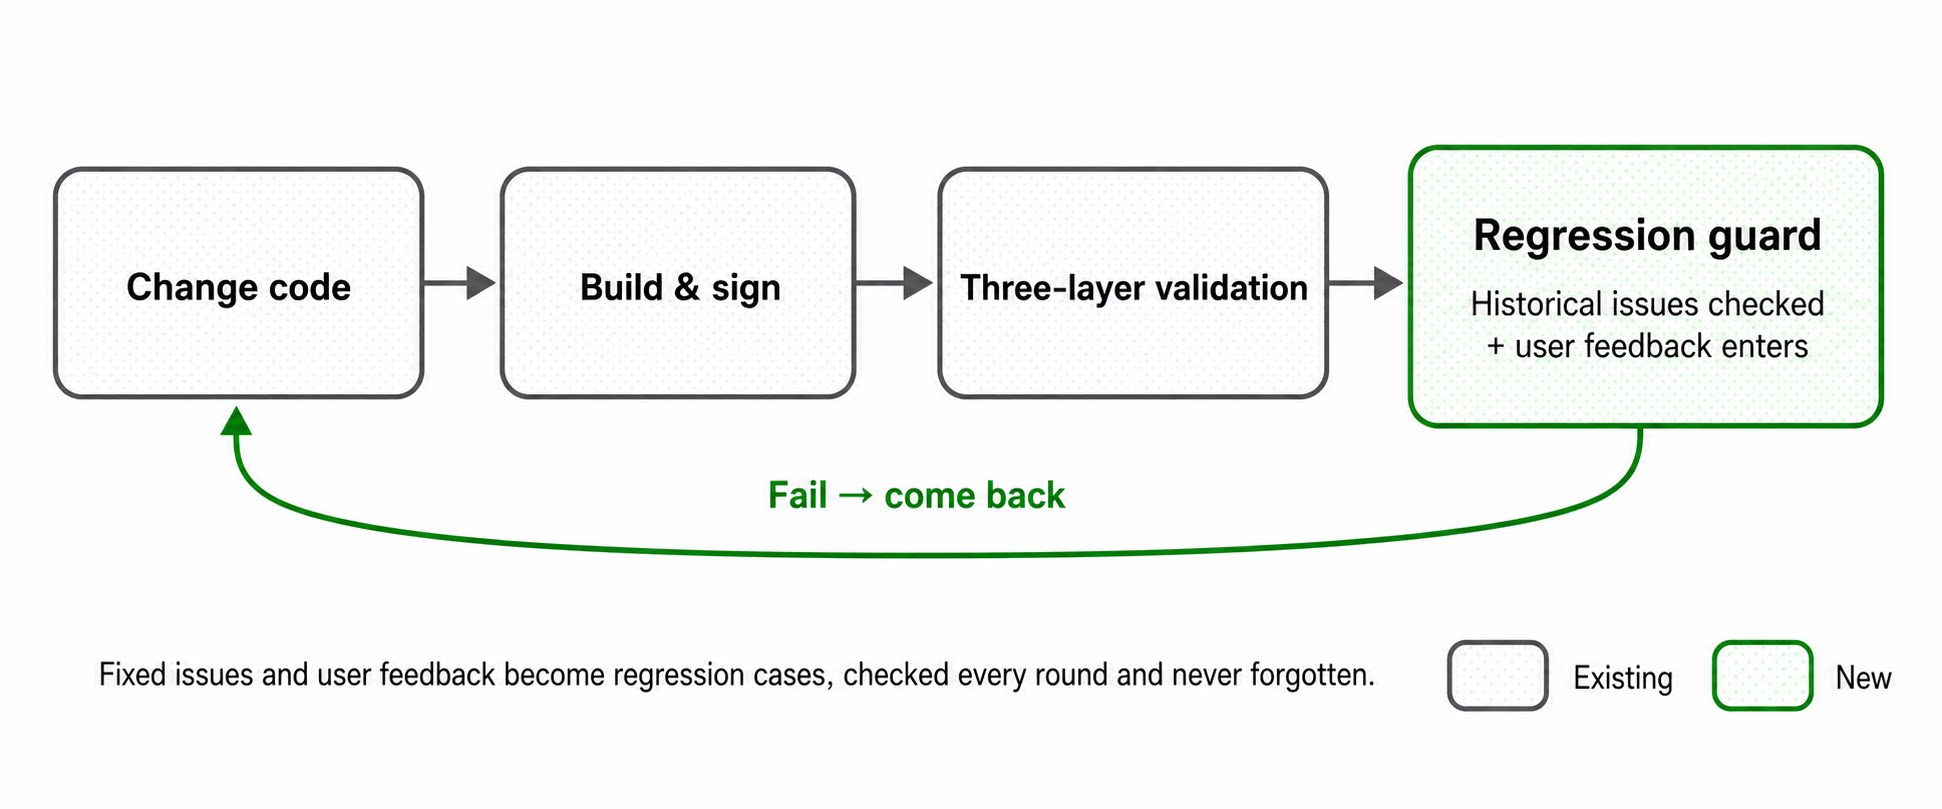
The answer is straightforward: every fixed issue becomes a persistent test case and gets checked automatically in future rounds. We went one step further. Bugs discovered during development enter the regression suite, and so does real user feedback. A report like "clicking did not work in this app" becomes a repeatable scenario and permanently joins the regression set.
Problems that have already happened should not live only in human memory. They should become automatic checks.
Here are two real examples:
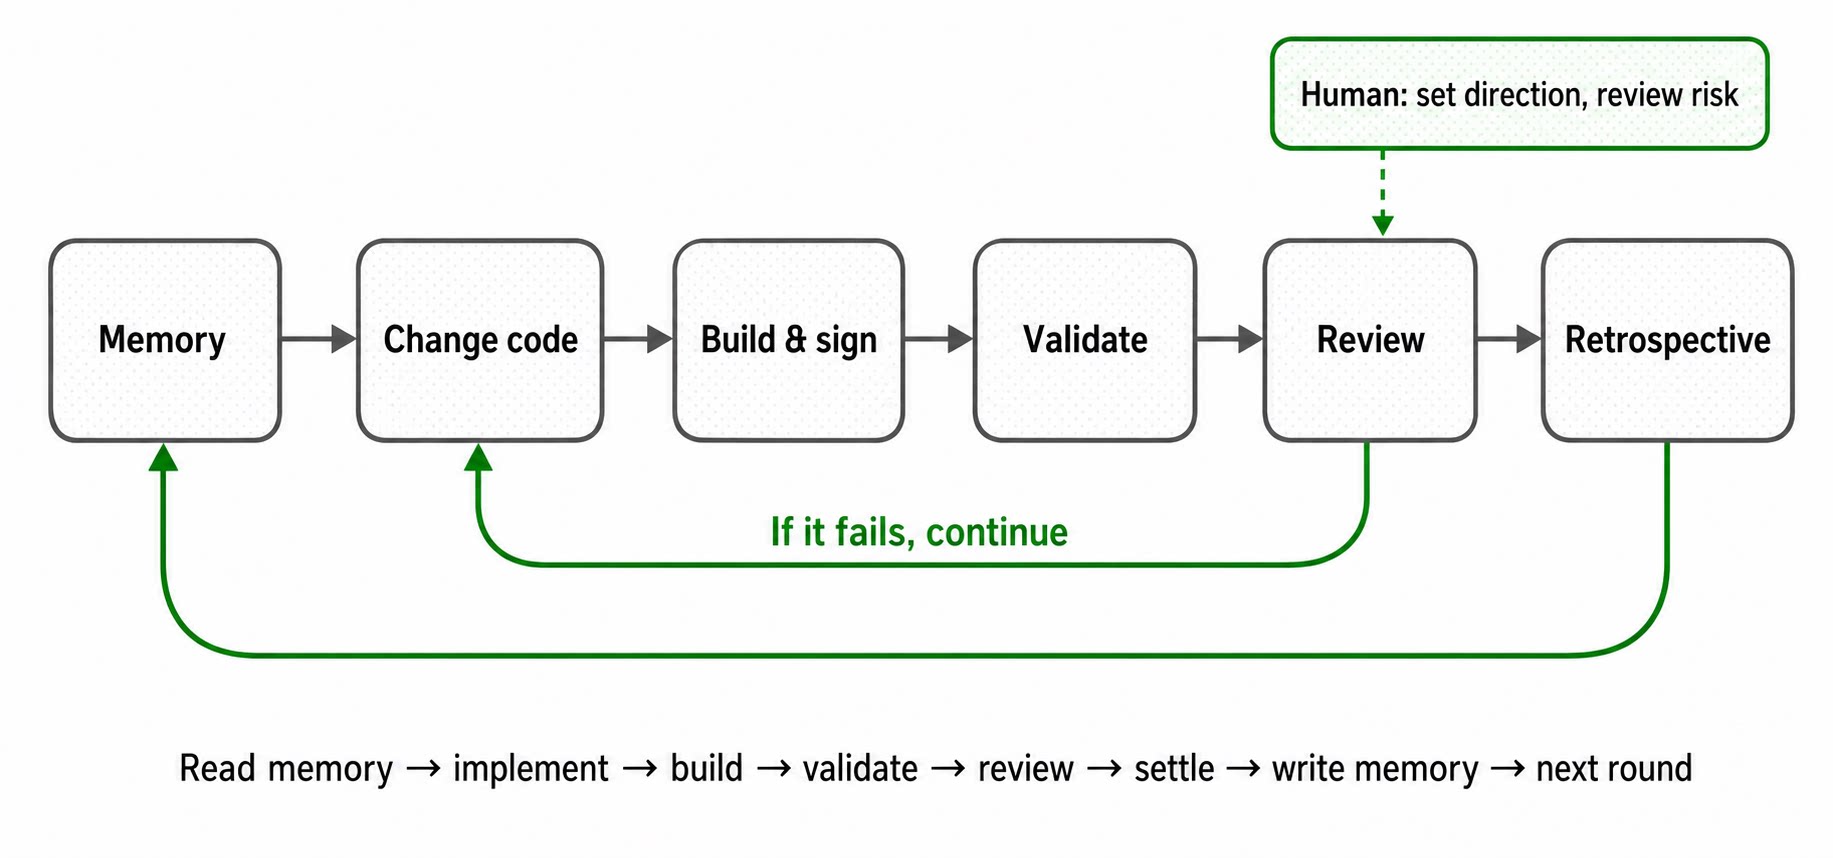
At the start of each round, the Agent reads project memory and the previous retrospective. At the end, it writes back.
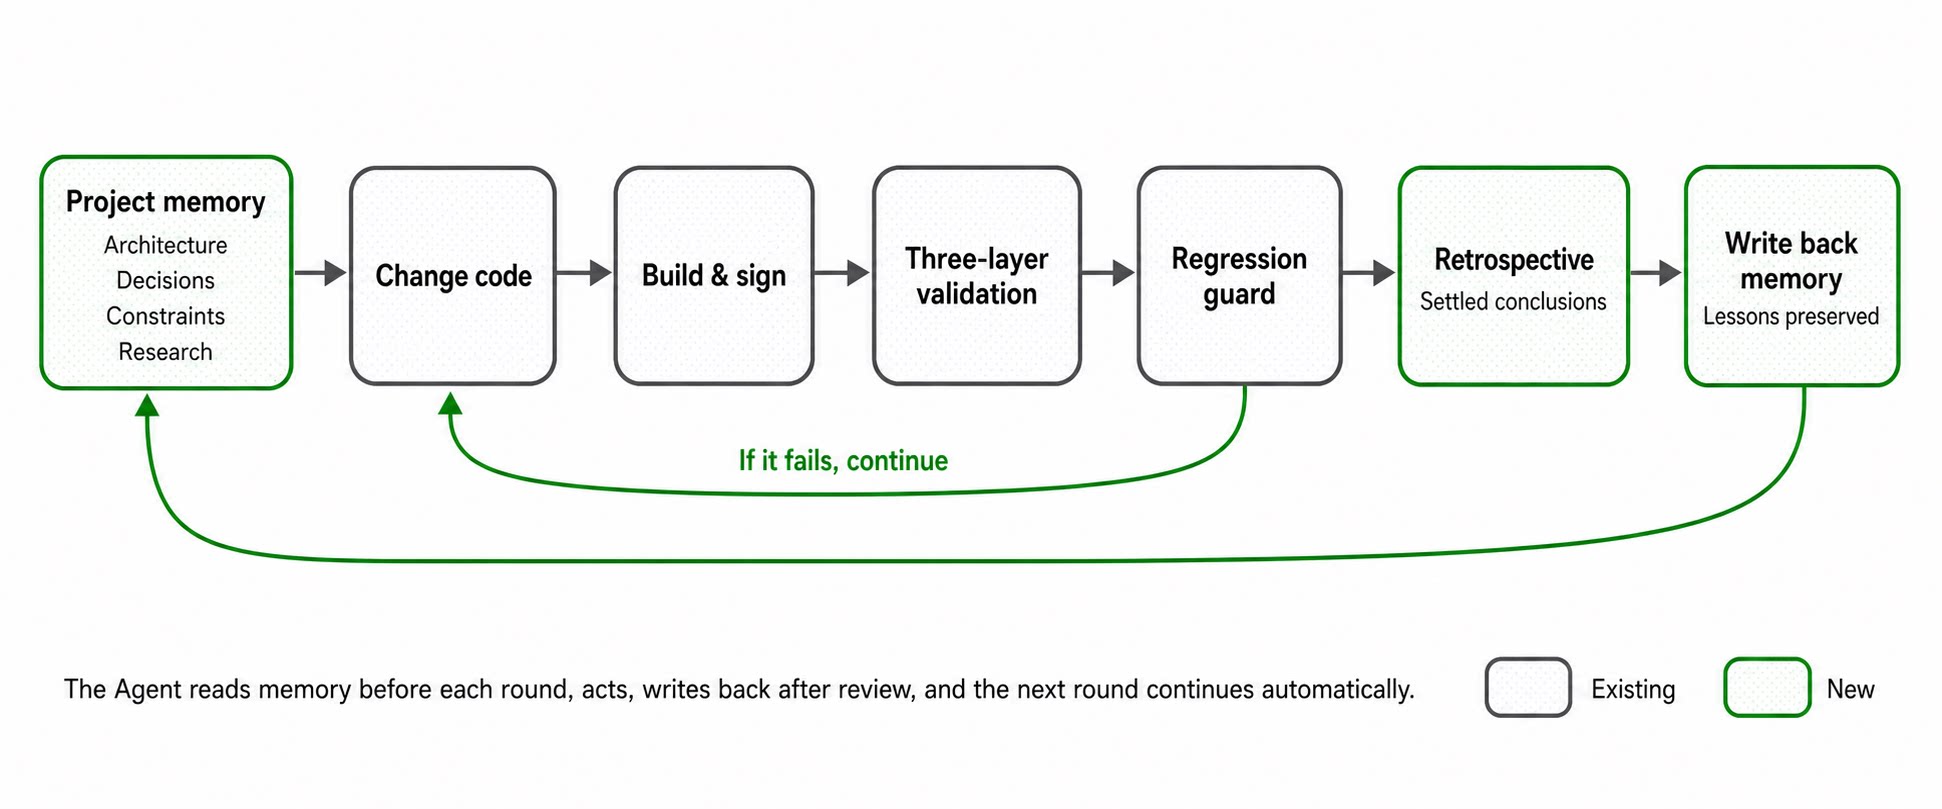
Put together, the system forms a complete loop:
Goal → Implementation → Verification → Retrospective → Next goal
Each round no longer starts from zero. It starts from everything the previous round has already learned.
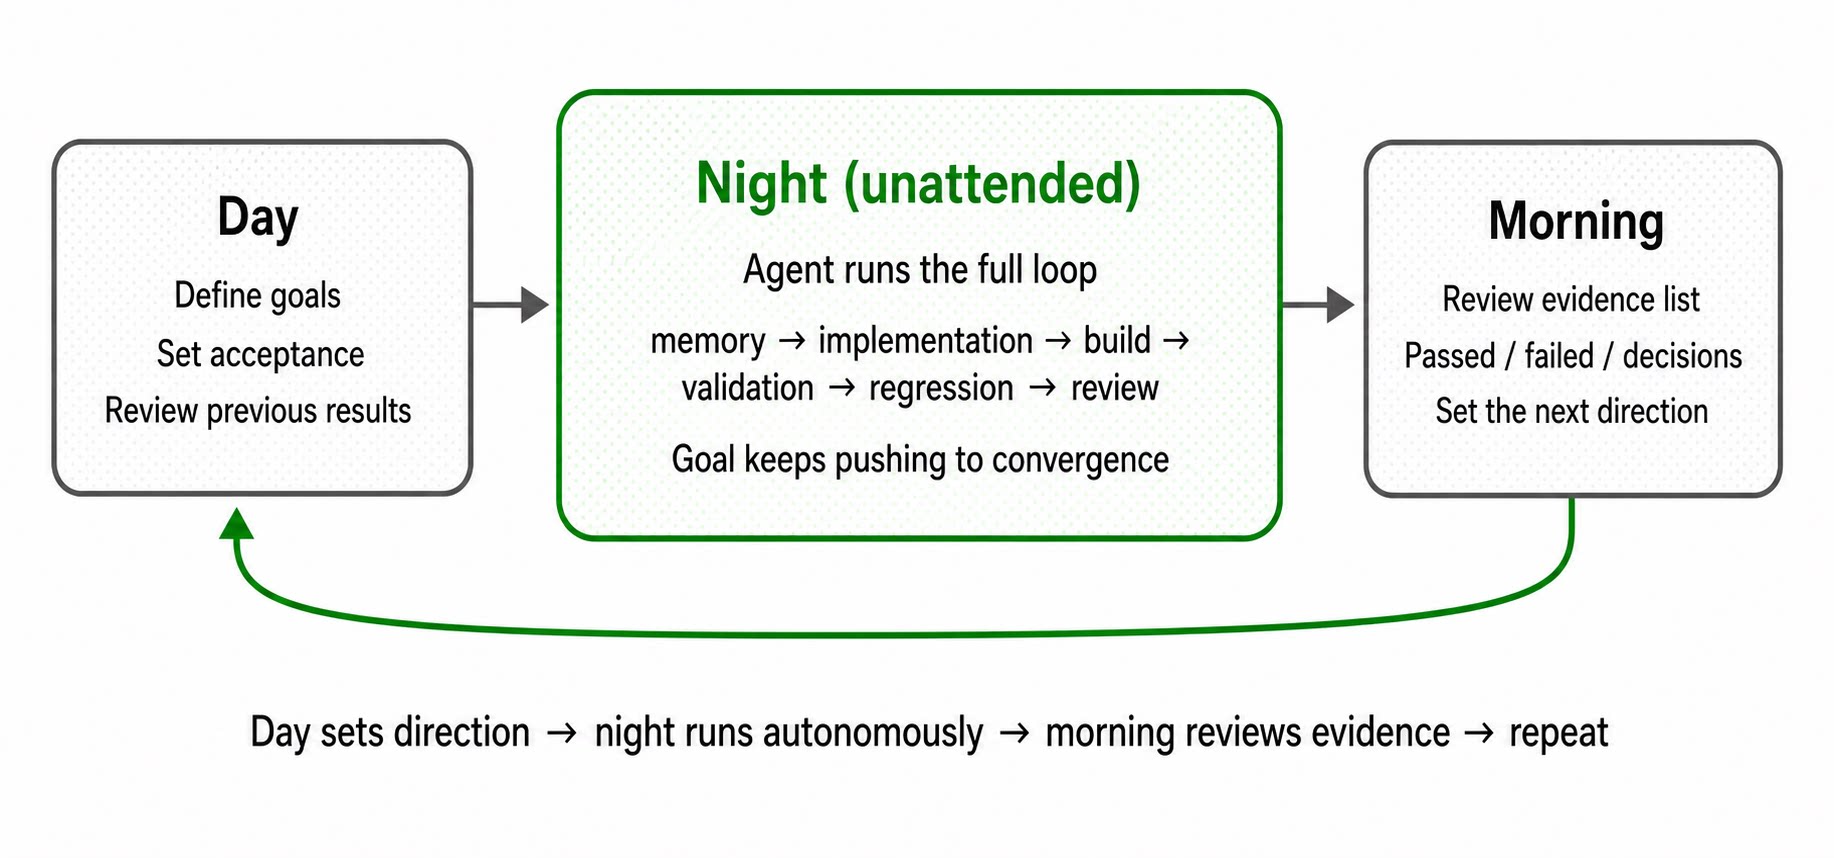
Once the loop is in place, it no longer requires a human to watch it in real time:
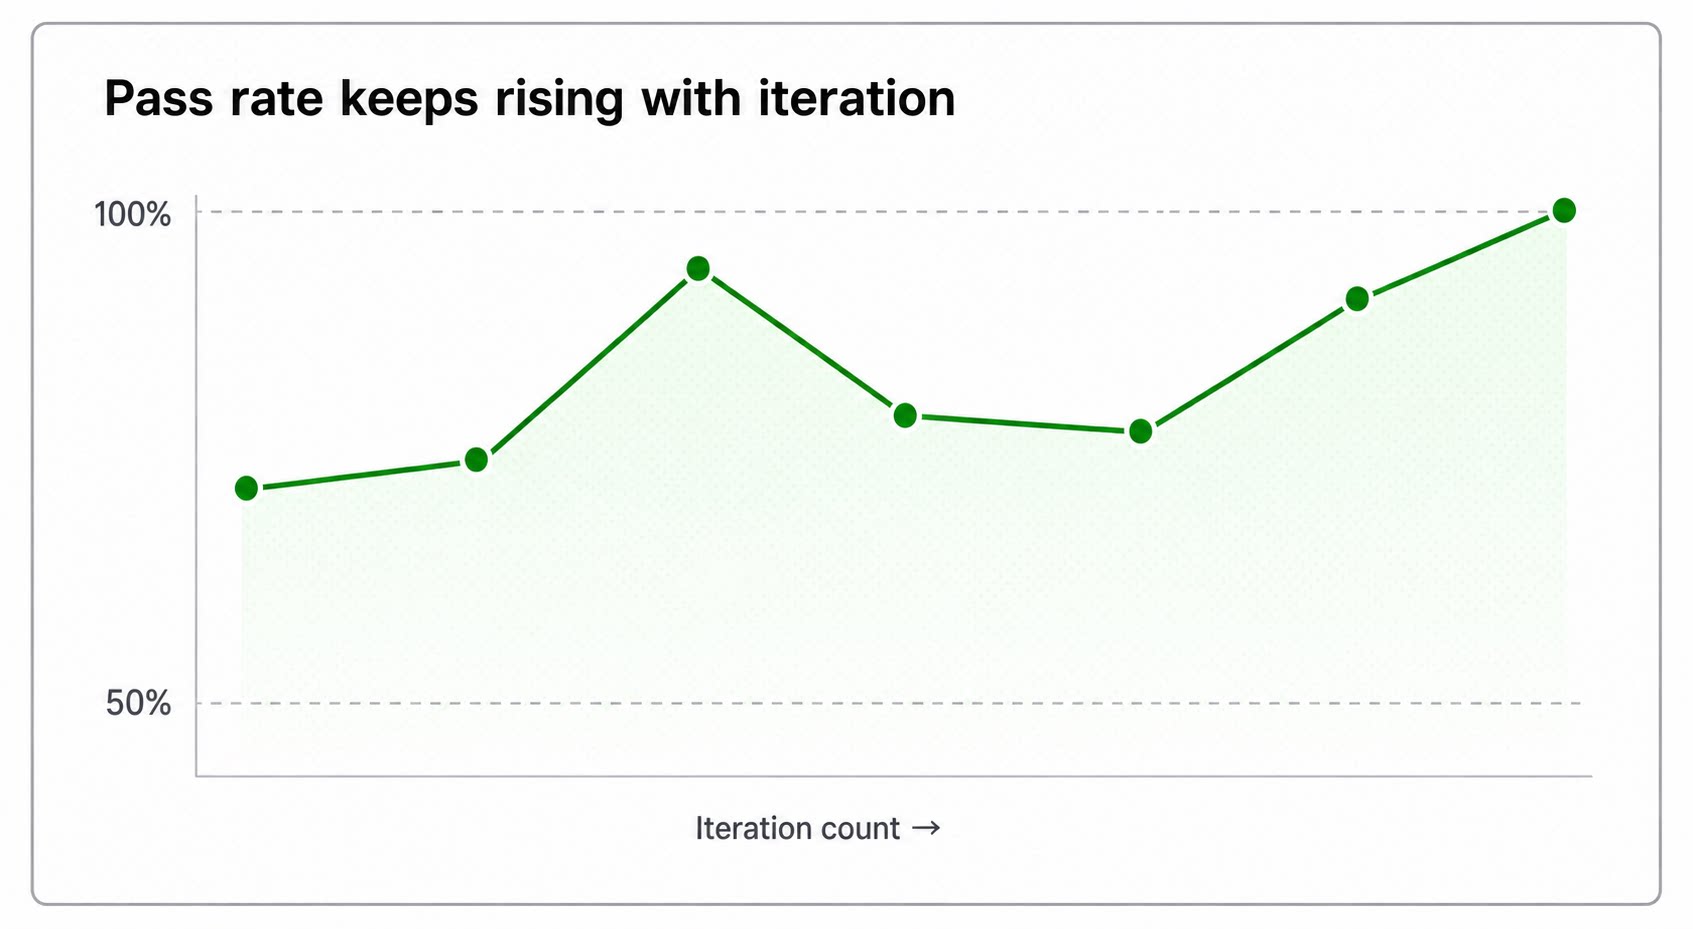
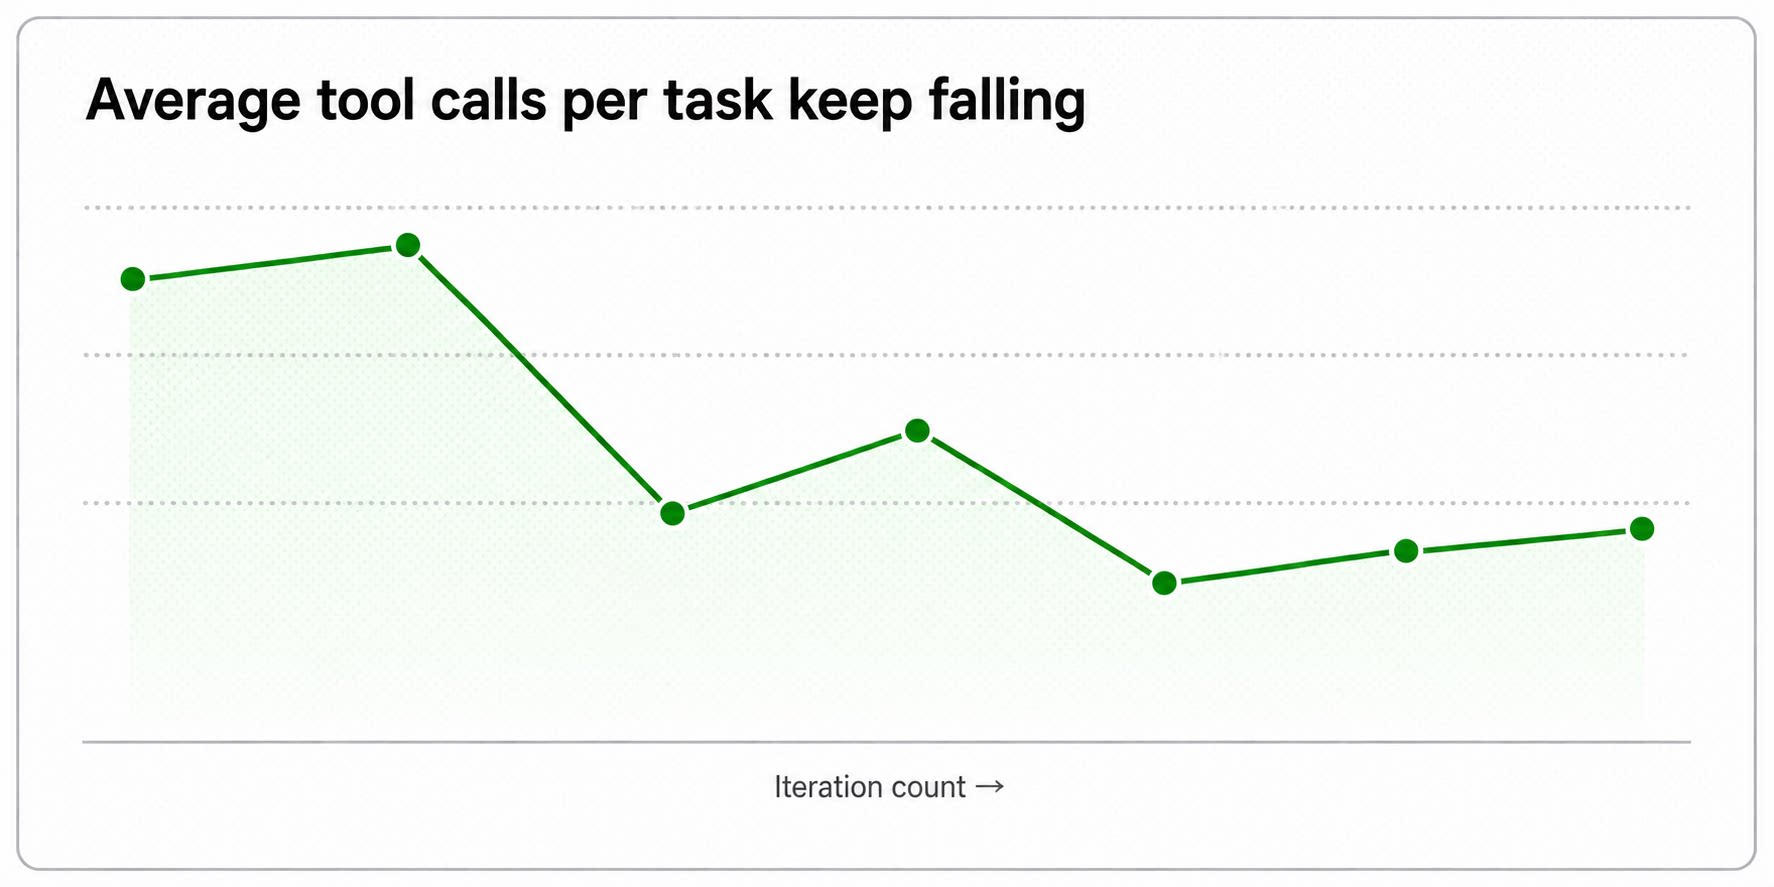
This system has run for hundreds of hours of continuous iteration, including a large amount of unattended overnight work. The two charts below show real evaluation data.
Back to the original problem: one person who did not know Swift had to deliver production-grade native macOS software. In the end, it worked. The reason was not simply that AI was powerful. It worked because we built a system around acceptance, testing, memory, and regression. Inside that system, AI could run, verify, and accumulate knowledge by itself.
The human role shifted from "write code and watch execution" to "define standards, design verification, and choose direction." Recently, the term "Loop Engineering" has become popular. When we saw it, we realized that this is exactly the practice we had already been using inside Qoder.
Once this loop works, an engineer no longer has to be an expert in a specific technology stack to deliver production-grade software. The technology stack is no longer the main barrier. The real leverage is the ability to define the target and verify the result.
Qoder Desktop already includes Goal Mode and Spec capabilities, and the latest release upgrades UltraPlan and UltraReview. Together with general-purpose validation tools such as Computer Use and Browser Use, they can help you build your own autonomous iteration system much faster.
- A technology gap. The work required Swift and native macOS APIs. No one on the team was familiar with macOS development, and I personally did not know Swift at all.
- A large scope with limited people. ComputerUse spans semantic UI-tree operations, screenshots, inter-process communication, permissions, signing, action replay, and a full set of system capabilities. Traditional manual development would not scale. The question was not "can we build it?" but "how do we use Qoder to maximize AI's leverage and multiply engineering output?"
- A very high bar for quality. This was not a demo. It had to be useful in real Agent workflows, where a weakness in any dimension would immediately become visible.
Removing the Human from the Loop
The first workflow was very traditional: I wrote the requirement, the Agent wrote code, I manually ran tests, inspected the result, and then gave feedback.
If you have used AI coding assistants, this probably feels familiar. Every conversation starts from zero. You have to restate the context, explain how to test, and remind the Agent which directions have already failed. The Agent may be capable, but without persistent memory, each round feels like working with a new person.
The bottleneck is the human. Human attention is limited and discontinuous. When the human stops, the system stops. To keep iterating, the system has to be able to run on its own.
Automation Pipeline + Goal Mode
To make the Agent iterate autonomously, the first step was to build a pipeline it could complete by itself.
ComputerUse depends on system permissions. Every build has to be signed with the same certificate; otherwise macOS treats it as a new application and invalidates the previously granted Screen Recording and Accessibility permissions. We wrapped the entire path from source build, to stable signing, to launch, to tests. The Agent can run the full path with one command. It does not need to understand signing details; it only needs a reliable route to a behaviorally valid package.
Being able to run once is not enough. A normal Agent conversation is request-and-response: once the task is done, it stops. But building a tool often requires many turns before it converges. Compilation fails, tests fail, behavior is wrong in one app, or a fix causes a regression elsewhere. If a human has to restart every round, the efficiency collapses.
We used Qoder Goal Mode. You give the Agent a goal, such as "implement the click tool and pass the end-to-end test." It keeps working toward that goal: implement, test, fix failures, and try again until it either succeeds or clearly needs a human decision. It no longer "runs once and stops"; it loops until the target converges.
Self-Verification
Once the Agent could run by itself, a new problem appeared quickly.
For example, we asked the Agent to implement the click tool. It ran the test and reported success. But when we checked manually, the button had not actually been clicked. The test only checked that the call did not throw; it did not check that the button state changed. The test was green, but the real behavior was wrong.
The issue was not that tests were missing. The issue was that the tests were too weak. If a test only covers the happiest path, the Agent can write an implementation that does nothing and still "pass." We changed the rule: no change is complete unless it passes real and sufficient verification.
That verification has three layers:
- Unit tests: validate individual pieces of logic.
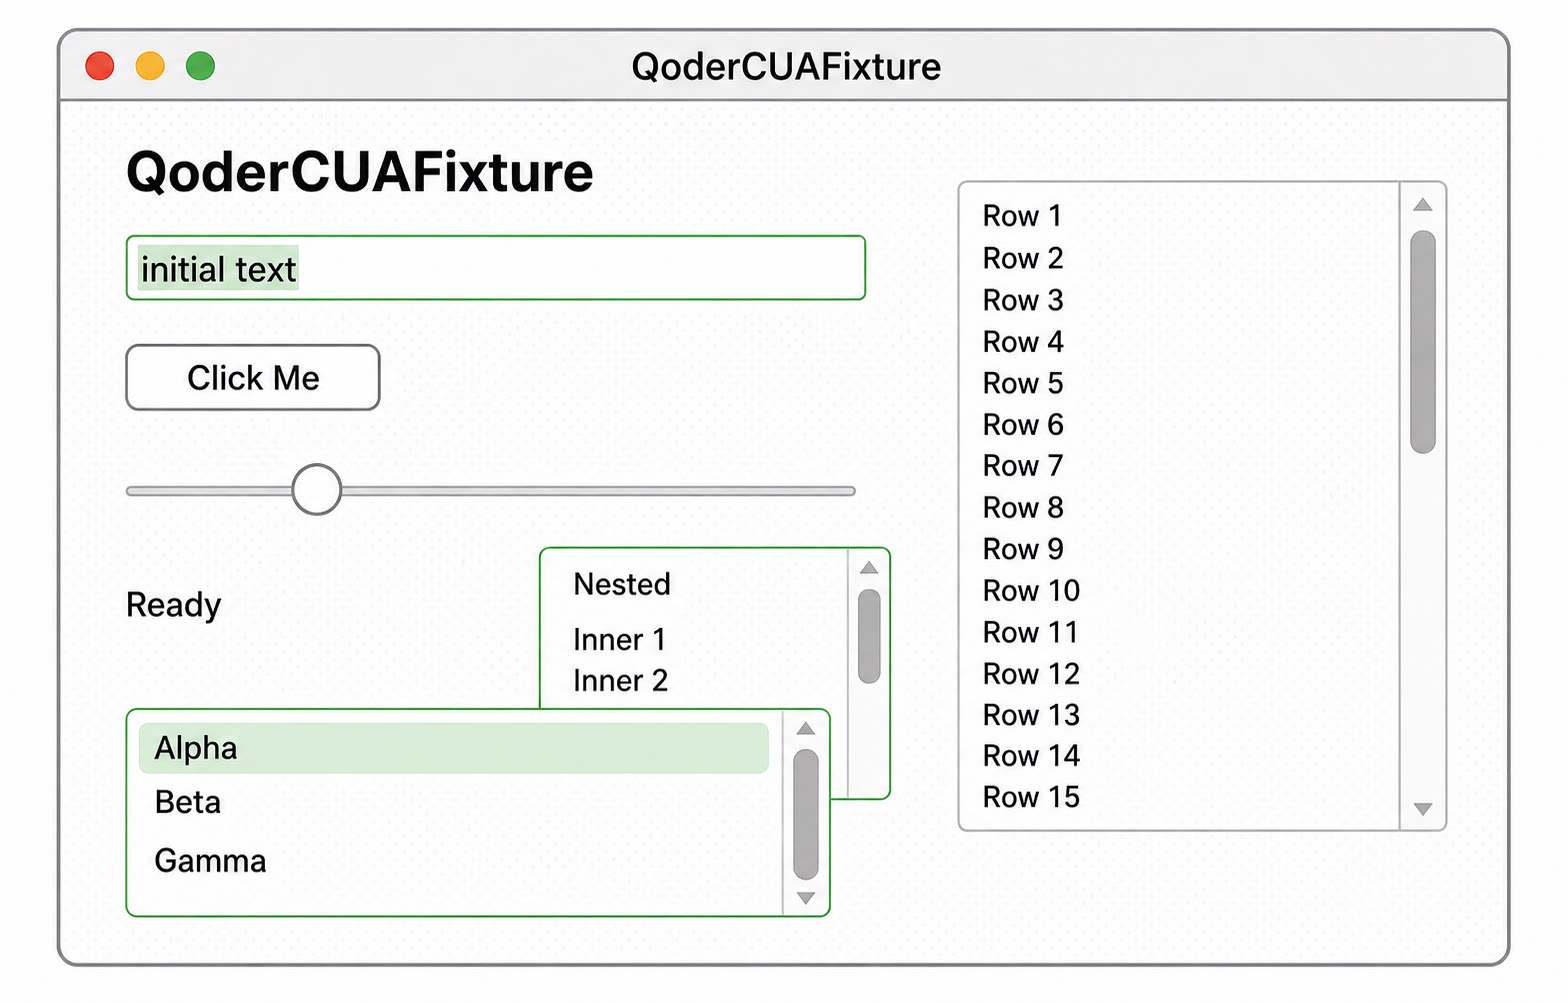
- Functional tests: the Agent builds a test app and runs the tool end to end to prove that it works on a real interface.
- Evaluation set: standard scenarios measure whether the overall system regresses.
Regression Guards
Verification lets the Agent prove that the current change works. But it does not automatically protect against another class of failure.
Suppose we fix an issue on Monday: clicking a button sometimes steals foreground focus. On Wednesday, the Agent optimizes another feature and accidentally changes related logic. The old issue comes back, but no one notices because it is outside the current task's test scope.
The answer is straightforward: every fixed issue becomes a persistent test case and gets checked automatically in future rounds. We went one step further. Bugs discovered during development enter the regression suite, and so does real user feedback. A report like "clicking did not work in this app" becomes a repeatable scenario and permanently joins the regression set.
Problems that have already happened should not live only in human memory. They should become automatic checks.
Project Memory
Here are two real examples:
- We had established that every build must use a stable signing certificate. In a later round, a new Agent saw a temporary local signing script and used it directly. The permission prompts came back because it had no idea about the earlier constraint.
- In a previous round, an Agent had tried replacing scroll with a system-level API, found that it was unstable in some apps, and rolled it back. That "already tried and failed" conclusion was not written down, so the next round proposed the same approach and repeated the detour.
The Full Loop
Put together, the system forms a complete loop:
Goal → Implementation → Verification → Retrospective → Next goal
Each round no longer starts from zero. It starts from everything the previous round has already learned.
Human Direction by Day, Autonomous Iteration by Night
Once the loop is in place, it no longer requires a human to watch it in real time:
- Day: the human sets the next goal and acceptance criteria, then reviews the previous result.
- Night: the Agent runs automatically: implementation, testing, evaluation, and retrospective.
- Morning: the human reads an evidence list: what passed, what failed, and what decisions are needed.
After Hundreds of Hours
This system has run for hundreds of hours of continuous iteration, including a large amount of unattended overnight work. The two charts below show real evaluation data.
A New Way to Build Software
Back to the original problem: one person who did not know Swift had to deliver production-grade native macOS software. In the end, it worked. The reason was not simply that AI was powerful. It worked because we built a system around acceptance, testing, memory, and regression. Inside that system, AI could run, verify, and accumulate knowledge by itself.
The human role shifted from "write code and watch execution" to "define standards, design verification, and choose direction." Recently, the term "Loop Engineering" has become popular. When we saw it, we realized that this is exactly the practice we had already been using inside Qoder.
Once this loop works, an engineer no longer has to be an expert in a specific technology stack to deliver production-grade software. The technology stack is no longer the main barrier. The real leverage is the ability to define the target and verify the result.
Qoder Desktop already includes Goal Mode and Spec capabilities, and the latest release upgrades UltraPlan and UltraReview. Together with general-purpose validation tools such as Computer Use and Browser Use, they can help you build your own autonomous iteration system much faster.